A technical account published by Quanta Magazine has revisited the attention mechanism that underpins transformers and today's large language models, tracing it to a machine-translation problem tackled in 2014. The story centers on researcher Dzmitry Bahdanau, who was then working with Yoshua Bengio and Kyunghyun Cho at the University of Montreal.
Neural translation systems at the time struggled as sentences grew longer. Their architectures attempted to compress an entire source sentence into a fixed-size representation before generating the translation, creating a bottleneck that discarded useful context. Bahdanau's approach let the network consult different parts of the source while producing each output word, assigning greater weight to the pieces most relevant at that moment. The team called the operation attention.
The practical value is clearest when meaning depends on distant context. A pronoun can refer to different nouns depending on the rest of a sentence, and a correct translation may require choosing a gendered form in the target language. Attention gives a model a mathematical way to identify which surrounding words should influence the next output rather than relying on one compressed summary of everything that came before.
The mechanism later became the central component of the transformer architecture introduced by Google researchers in 2017. That design removed the recurrent structures common in earlier sequence models and used attention throughout. The resulting system reached leading translation performance while reducing the computation needed for training, according to the account. Transformers subsequently became the architecture behind large language models including ChatGPT and Claude.
Inside a transformer, each token is represented as a vector. Learned weights turn that representation into three more vectors commonly called a query, key and value. An attention head compares a token's query with the keys associated with other tokens. The strength of those matches determines how much of each corresponding value is incorporated into an updated representation. Multiple heads perform this process in parallel, allowing different relationships in the text to be modeled at once.
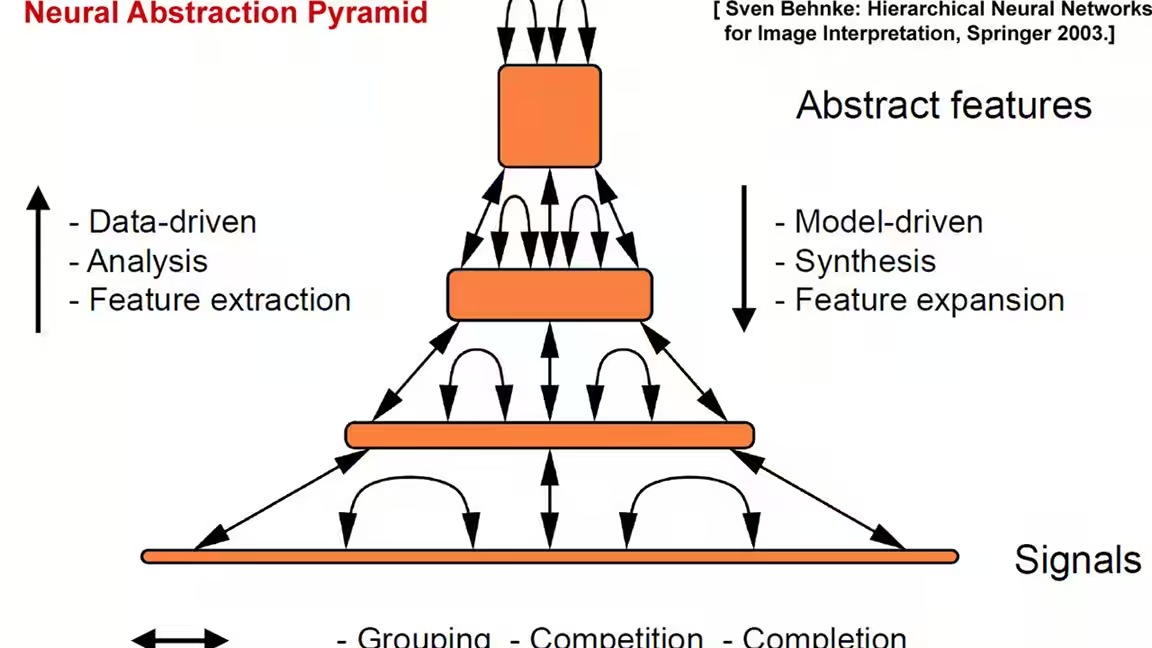
This construction does not mean an AI system pays attention in the human psychological sense. It is a numerical routing operation that selectively mixes contextual information. Its importance comes from scalability: each token can directly draw on relevant information elsewhere in the sequence, and the operations can be parallelized efficiently during training.
The historical path from translation to general-purpose models also cautions against treating one mechanism as a complete theory of intelligence. Attention solved a specific engineering bottleneck and proved unusually reusable. Its reach across text generation and other AI tasks shows how a well-chosen computational primitive can become foundational without, by itself, explaining cognition.